
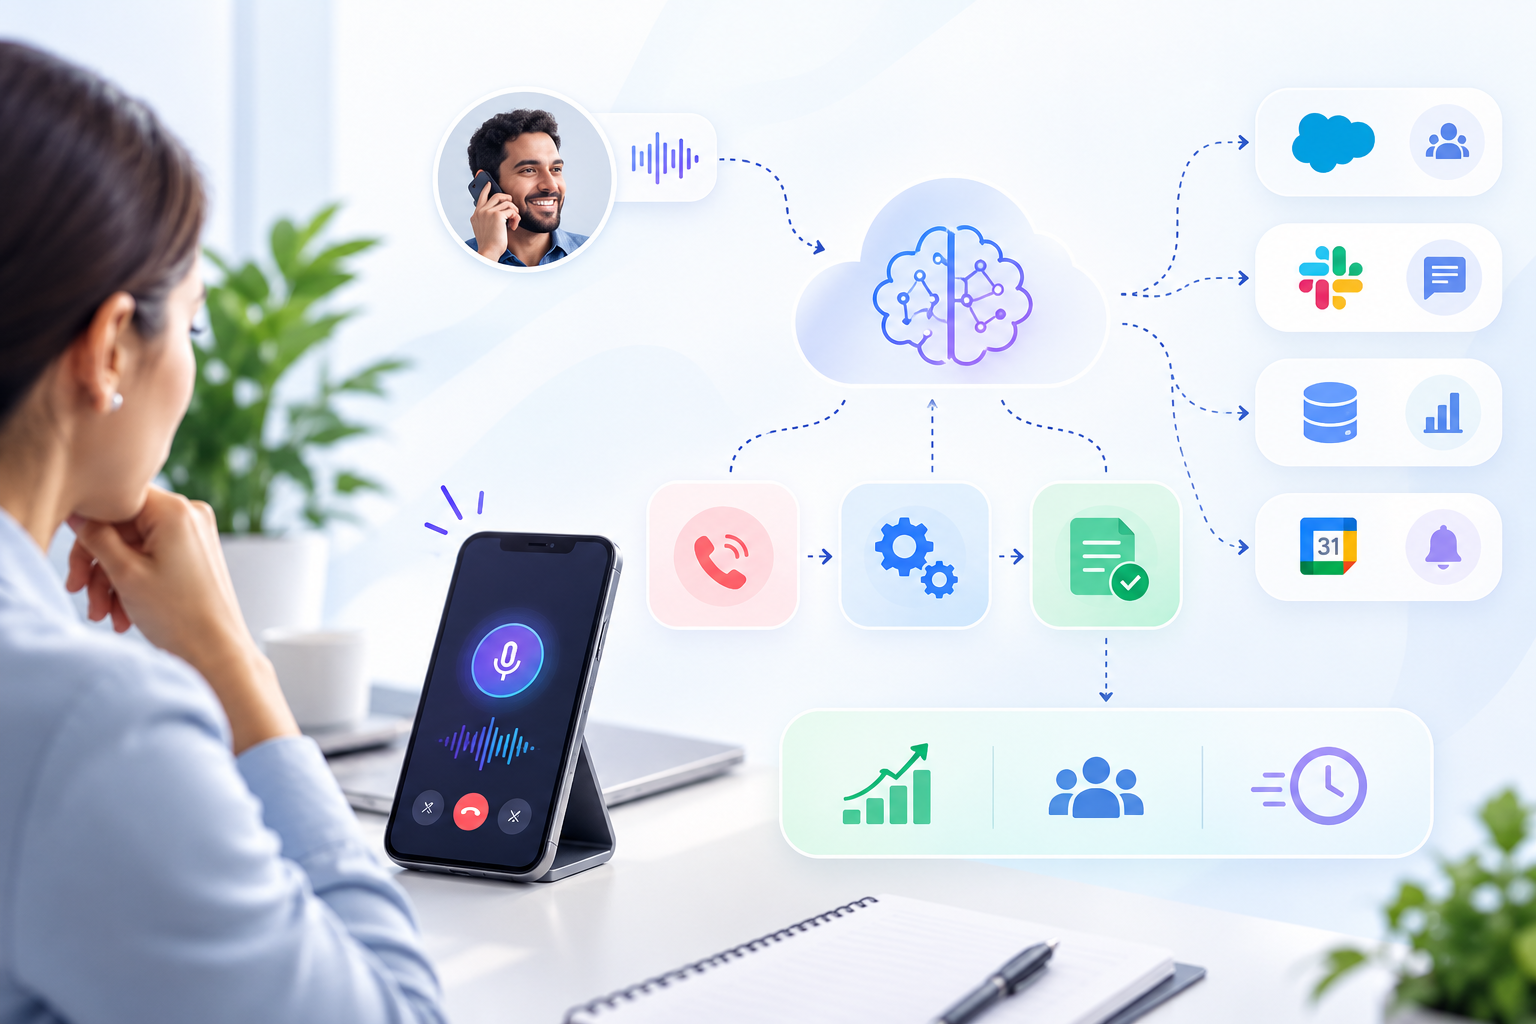
Building modern artificial intelligence systems in 2026 is no longer a question of training a larger foundation model or writing clever prompt wrappers. The industry-wide pivot toward autonomous workflows has transformed how engineering teams approach core architecture.
When transitioning from experimental sandboxes to enterprise-grade operations, the primary engineering challenges shift from raw intelligence to real-time reliability, multi-system orchestration, security isolation, and sub-second latency.
This guide explores what AI infrastructure actually looks like in production today, how enterprise requirements evolve, and how technical teams scale low-latency real-time voice architectures.
What Is AI Infrastructure in 2026?
Modern AI infrastructure refers to the integrated stack of hardware, network, data pipelines, orchestration platforms, and monitoring frameworks required to deploy, execute, and scale artificial intelligence workloads in production.
While legacy machine learning infrastructure focused heavily on offline batch training and static feature stores, modern agentic AI infrastructure is engineered for continuous real-time inference, dynamic decision-making, external tool invocation, and low-latency state management.
The Modern AI Infrastructure Stack:
Security and Compliance: Encryption, Data Isolation, SOC2/HIPAA, RBAC
Orchestration Layer: Agent Frameworks, Context Management, Tool Execution
Inference Engine: Specialized Compute (GPUs/TPUs), Model Serving APIs
Data Pipeline Layer: Vector DBs, Real-Time Streams, Telephony/SIP Trunks
Compute and Hardware: Cloud Providers, Edge Nodes, Specialized Accelerators
What Does Modern AI Infrastructure Actually Look Like?
Building AI infrastructure for enterprises requires balancing non-negotiable architectural requirements across scale, security, and continuous execution.
Enterprise Requirements:
Moving From Prototype to Production:
The transition from a working proof-of-concept (POC) to production-grade deployment exposes immediate structural bottlenecks:
1. Execution Context:
- Experimental Prototype: Single-turn API calls
- Production Enterprise: Multi-step agentic execution and tool invocation
2. Failure Handling:
- Experimental Prototype: Basic try/catch logic
- Production Enterprise: Fallback routing, graceful degradations, warm transfers
3. State Management:
- Experimental Prototype: Ephemeral, local session storage
- Production Enterprise: Distributed state, persistent vector stores, context preservation
4. Observability:
- Experimental Prototype: Console logs
- Production Enterprise: End-to-end telemetry, token tracking, latency profiling, audit logs
How to Scale AI Infrastructure
Knowing how to scale AI infrastructure effectively requires optimizing four main dimensions:
How to Scale Voice AI Infrastructure
Scaling voice-based autonomous workflows introduces a unique, unforgiving engineering constraint: audio must be processed in real time without human-perceptible lag.
Executing this pipeline smoothly requires every node to communicate within tight time constraints.
Latency: The Critical Metric for Real-Time AI
In conversational systems, turn-taking delay determines human perception. Standard web applications accept 2-3 second latency, but human conversation breaks down if lag exceeds 800 milliseconds.
Key latency optimizations include:
- Full-Duplex Telephony: Allowing continuous audio streaming so systems can process interruptions (“barge-in”) instantly.
- Streaming STT and TTS: Processing audio chunks concurrently rather than waiting for complete sentences.
- Speculative Execution: Pre-fetching context and warming API connections based on predictive intent recognition.
Security, Compliance, and Cost Governance
Deploying enterprise-grade autonomous systems requires strict operational safeguards:
Data Isolation and Encryption: End-to-end encryption for data in transit (TLS 1.3) and at rest (AES-256), combined with strict tenant isolation.
Access Control and Secrets Management: Fine-grained API authorization rules, key vault management, and automated rotation.
Monitoring and Auditability: Comprehensive logging of model decisions, API executions, and human handoff events.
Cost Drivers: Managing token usage, compute instance hours, streaming bandwidth, and telephony trunking costs to ensure healthy unit economics.
According to research published by Gartner, operational cost management and security readiness remain primary determinants of enterprise AI project longevity.
Future Trends: Agentic Workloads and Distributed Compute
The future of infrastructure is shifting rapidly toward agentic AI infrastructure. Key directions shaping the landscape include:
- Multi-Agent Orchestration: Specialized micro-agents working in tandem to resolve complex tasks.
- Edge Inference Deployment: Running speech and lightweight language models closer to the end user to eliminate network hop latency.
- Self-Optimizing Workflows: Autonomous infrastructure that re-routes calls based on real-time network conditions and compute pricing.
Building scalable voice infrastructure for your enterprise? Book a Demo with our AI VoiceOps team today: https://aivoiceops.bugendaitech.com/book-demo/
See the complete call journey on your own scenario.
Bring one real inbound or outbound use case. We’ll show how AI VoiceOps can handle the conversation, action and post call follow up in one connected flow.